Aleph Alpha

Meet Kolibri

Made in Germany. Built for the world.

  • Mission critical performance

    Built to perform in high-impact use cases, including assistants and agentic workflows that need multi-step reasoning, structured extraction, retrieval-augmented generation and reliable tool calling.

  • Control by design

    Trained end-to-end from scratch by our teams in Germany, with full supply-chain integrity. Your operations stay independent with freedom of deployment, IP safety and no imported bias.

  • Native German and English

    Specialized in German on our in-house carefully curated German-language data. The model understands how both German and English speakers work with the relevant domain context included.

  • Compliant for regulated work

    Strictly aligned with European legal and regulatory standards including the EU AI Act and Codes of Practices. Our model is ready for even the most sensitive workloads in public sector and industry.

Performance

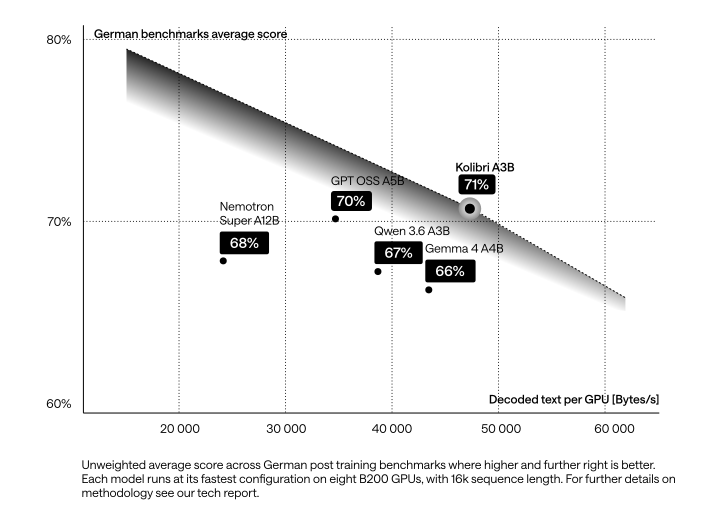
Scatter chart: German benchmarks average score (%) against decoded text per GPU (bytes/s). Kolibri A3B reaches 71% at about 47,000 bytes/s and sits on the efficiency frontier. GPT OSS A5B: 70% at about 34,500. Nemotron Super A12B: 68% at about 24,000. Qwen 3.6 A3B: 67% at about 38,500. Gemma 4 A4B: 66% at about 43,000.

Efficiency
on the pareto frontier

Smaller by design, efficient by default.

Kolibri performs comparably to larger models while generating more text output per GPU. The result is cost efficiency, reduced energy consumption, and faster, more scalable deployments.

  • Using Tools & Agents

    What this means

    Measures how well the model handles multi-step conversations and correctly operates external tools and systems to complete a task.


    Use case

    Power citizen-service agents that work through requests end-to-end, like retrieving a record, looking up eligibility criteria, or filling in a form.

    Interactive chart. Arrow keys left and right move between benchmarks, up and down between models. Enter highlights a model, Escape clears the selection.

    Using Tools & Agents
    Benchmark KolibriQwen3.6 35B-A3BMistral Small 4 119B-A6BNemotron 3 Super 120B-A12B
    Tau2-Bench (Telecom) 94.7%99.1%41.5%68.1%
    Tau2-Bench (Retail) 69.9%71.6%62.9%67.5%
    Tau2-Bench (Airline) 76.7%70.7%40%72.7%
    Tau3-Bench (Banking) 38.1%10.6%5.7%15.5%
    BFCL v4 (overall) 61.4%67.2%58%61%
  • German Language Skills

    What this means

    Measures how well the model reasons, calculates, and follows instructions in German language.


    Use case

    Citizen requests and official correspondence work in administrative German with the same quality you’d expect in English.

    Interactive chart. Arrow keys left and right move between benchmarks, up and down between models. Enter highlights a model, Escape clears the selection.

    German Language Skills
    Benchmark KolibriQwen3.6 35B-A3BMistral Small 4 119B-A6BNemotron 3 Super 120B-A12B
    GPQA Diamond (DE) 81.3%80.6%72.9%76.6%
    Humanity's Last Exam (DE) 15.9%20.5%10.5%22.3%
    MMLU-ProX CoT (DE) 75.5%81.9%70.7%79.7%
    AIME 2025 (DE) 87.5%82.9%72.3%85.6%
    AIME 2026 (DE) 90%84.4%78.5%87.5%
  • Reasoning & Analytical Tasks

    What this means

    Measures the model’s ability to solve hard problems in math and science that require deep, step-by-step thinking.


    Use case

    Supports analytical work in administration, such as planning calculations and policy assessment.

    Interactive chart. Arrow keys left and right move between benchmarks, up and down between models. Enter highlights a model, Escape clears the selection.

    Reasoning & Analytical Tasks
    Benchmark KolibriQwen3.6 35B-A3BMistral Small 4 119B-A6BNemotron 3 Super 120B-A12B
    GPQA Diamond (EN) 84.3%83.4%74.7%78%
    Humanity's Last Exam (EN) 21.5%21.1%9.7%20.6%
    AA-Omniscience Index (scaled public set) 33.6%42.35%38%31.75%
    MMLU-Pro CoT (EN) 80%84.3%80.4%82.7%
    AIME 2025 (EN) 96.9%84.6%79.8%91.7%
    AIME 2026 (EN) 96%91%83.1%90.4%

Model information

Status
Generally Available
Architecture
Mixture-of-Experts
Total parameters
78B
Active parameters per token
3B
Languages
German, English
Context length
1,048,576 (1m) tokens, 262,144 (256k) tokens recommended for serving efficiency and complex tasks
Precision
bfloat16
Reasoning mode
Yes (controllable)
Tool calling
Yes
Hardware requirements
  • Model memory footprint: ~78 GB (FP8 weights)
  • Minimum: 2× A100 80 GB, 2× H100 SXM5, 1× H200, 1× B200 or 1× B300
  • Recommended: 2× H100 SXM5, 2× H200, 1× B200 or 1× B300
Knowledge cutoff
EN: Jun 18, 2026, DE: Jun 18, 2026
Best for
  • Multi-step reasoning
  • Retrieval-augmented generation
  • Agentic tool calling
  • German- and English-language assistant
License
Apache 2.0
Sufficiently Detailed Summary
Read Summary

Use our model

Download the open weights from Hugging Face. Or contact our sales team who will be happy to support you through our enterprise deployment and specialization options.

Learn More

Dive deeper into the performance of our model in different capabilities. And understand our data curation, model architecture and training approach.